AI & Automation

Ship Production AI
That Actually Works

AI that ships to production, not just a demo. Outcome agreed upfront. Fixed base to deliver. Variable fee paid only if the metric lands.

What's included
Context engineering & LLM integration
RAG pipelines & knowledge bases
Agentic AI & loop engineering
MLOps & model deployment
AI-powered data pipelines
AI feasibility & strategy review
Typical engagement PoC in 2–4 weeks

Why do most AI projects fail before reaching production?

The gap between a ChatGPT demo and a production AI feature is wider than most teams expect. Here is what we see most often.

Hallucinations & unreliable outputs

The model works in the demo, then starts confidently producing wrong answers in production, with no way to know when it's happening.

PoC that never reaches production

Six weeks of build, a demo that impresses the board, then a realisation that latency, cost and security requirements weren't designed for from the start. What changes between demo and live →

Spiralling API costs

The PoC runs on GPT-4o for everything. By the time you're at scale, inference costs are 10× what anyone projected and there's no obvious lever to pull.

Free tool How much will your AI agents cost to run? →

No AI strategy or roadmap

Everyone agrees AI matters. Nobody agrees which problem to solve first, what success looks like, or whether the data you have is actually usable. AI production readiness guide →

What's included in TechTek's AI engineering service?

Six capability areas designed to move AI from experiment to a reliable, measurable part of your product. Not sure where you stand? Take our free AI Production Readiness Scorecard first.

Context engineering & LLM integration

Design the full context window: system prompts, retrieved chunks, tool schemas and conversation history. Integrates GPT-4o, Claude, Gemini or open-weight models with structured outputs and fallback logic.

RAG pipelines & knowledge bases

Retrieval-augmented generation over your documents, databases or APIs, so your AI answers with your own knowledge, not hallucinated facts.

Agentic AI & loop engineering

Design and build agentic systems with plan→act→observe loops, tool orchestration and multi-step reasoning, plus the harness engineering and human-in-the-loop checkpoints that make them production-safe.

MLOps & model deployment

Scalable inference infrastructure, model versioning, A/B testing and monitoring, so you can iterate safely on live AI features without downtime.

AI-powered data pipelines

Automated extraction, transformation and enrichment using AI for classification, entity extraction and summarisation at scale.

AI feasibility & strategy

A structured review of your use case, data quality, expected ROI and technical risk, giving you a clear recommendation before you invest.

What we've shipped

Case Study: Ecommerce & Retail

AI Customer Service Automation

High-volume customer support, handled end‑to‑end: email triage, order context, and drafted replies delivered in seconds. Agents step in only where it counts.
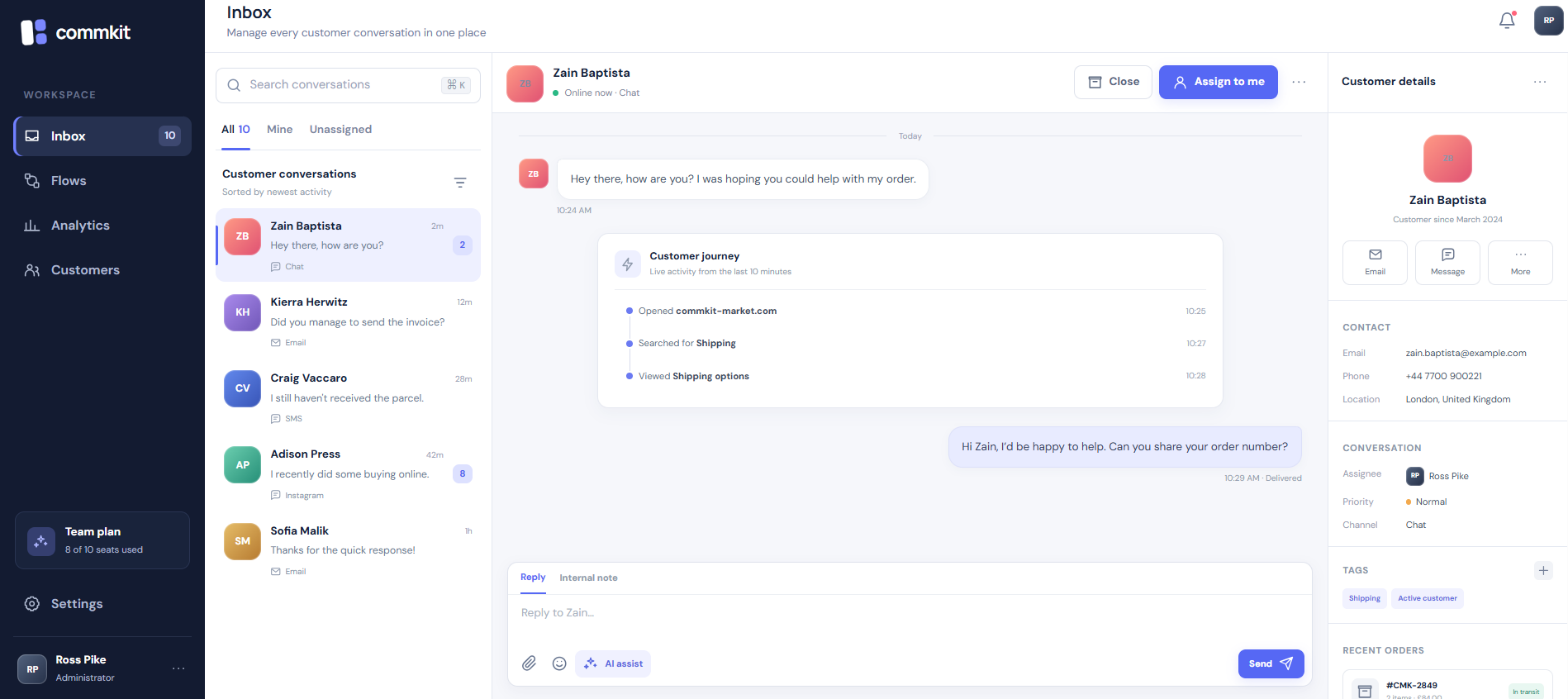
AI-assisted customer service inbox showing multi-channel conversations with order context and AI assist
8,429conversations handled per month
1m 18saverage first response time
94.6%customer satisfaction score
Case Study: Marketplace

Match AI

A hotel matching engine that reads trip requirements in plain English and returns ranked properties.

— Ranked properties delivered in under 1 second

— New property types added without rebuilding the model

View case study
Boutique hotel · Central London · Quiet · Pet-friendly · Work desk 3 results 1 The Covent Garden Inn 98% match "Boutique, quiet courtyard, central. Pet policy confirmed. Dedicated workspace in every room." Boutique Pet-friendly Covent Garden 2 The Marylebone Keys 91% "Boutique style, quiet side street. No formal pet policy; confirm on arrival. Work desk available." 3 The Shoreditch Standard 84% "Central, modern, work-friendly. No quiet courtyard. No pet accommodation confirmed."
<1sfrom guest preferences to ranked properties
1plain‑English reason per property, not a score
0rebuilds when a new property type is added
Case Study: MarTech

AI‑Native Content Operations

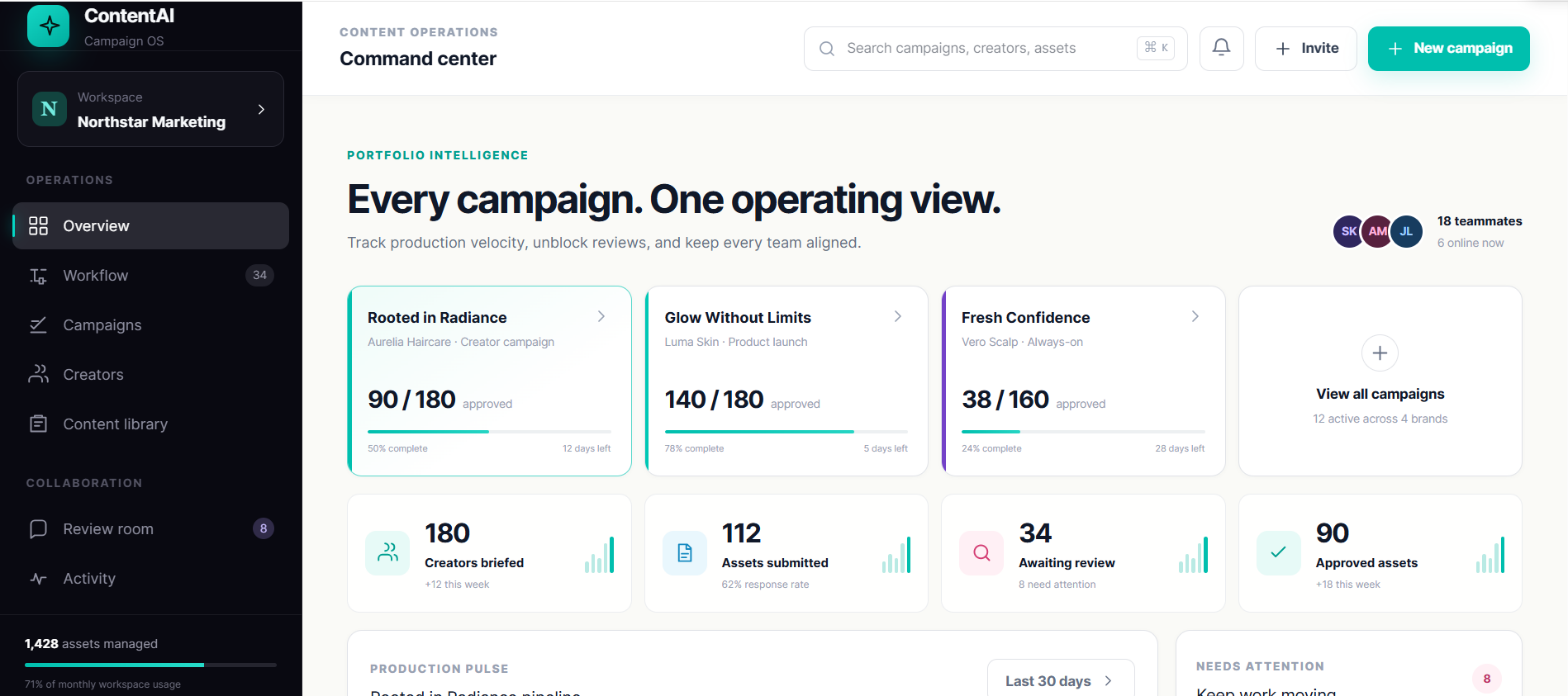
One platform for thousands of assets, managed at scale.

— 90 assets shipped through a single pipeline

— 12 brand accounts managed in one view
View details
ContentAI content operations dashboard showing creator asset pipeline, approval queue, and real-time production metrics
12brand accounts managed in one view
1,428assets tracked in real‑time
90assets approved and shipped

Outcome-based pricing

Tell us the outcome.
We'll price to it.

Fixed base fee to deliver. Variable fee paid only if the metric lands. We carry that risk.

Support tickets resolved without human escalation; target agreed upfront
Invoice or document processing time reduced by a defined %
Classification or accuracy target hit at scale in production
How our engagement model works

Outcomes we price to

% of AI requests resolved without escalation
Automation rate
Manual review or processing time cut by agreed %
Efficiency gain
Classification or extraction accuracy target at scale
Accuracy target

Baseline and target agreed during scoping. Measured at 60–90 days post-delivery using your own data.

Modern AI engineering stack, model-agnostic approach

We choose the right model and framework for your use case, not the most hyped one at the time.

Foundation Models

OpenAI GPT-4o Anthropic Claude Google Gemini Llama / Mistral

Frameworks & Orchestration

LangChain / LangGraph LlamaIndex CrewAI / AutoGen Python / FastAPI

Vector Databases & Search

Pinecone Weaviate pgvector Elasticsearch / OpenSearch

Infrastructure & Monitoring

AWS Bedrock / Azure OpenAI Google Vertex AI Langfuse / Helicone Modal / Replicate
AI Assistant · GPT-4o ● Live

Summarise the top issues from this week's support tickets

Analysis · 847 tickets · last 7 days

▸ Login & auth errors: 312 tickets (37%)
▸ Slow report exports: 198 tickets (23%)
▸ API rate limit hits: 141 tickets (17%)
Ask a follow-up…

AI projects sized for where you are now

Start with a low-commitment assessment, prove the PoC, then scale with confidence.

Fixed price

AI feasibility review

30-minute call plus a structured report covering use-case viability, data readiness, model options and estimated cost, delivered within 48 hours.

Time-boxed

Proof of concept

2–4 weeks to deliver a working prototype with baseline evals, a cost model and a clear recommendation on whether to proceed to production.

Monthly retainer

Production AI engineering

Ongoing AI development, monitoring, eval improvement and model upgrades, billed monthly with a capped sprint budget and named delivery lead.

Not sure about costs yet?

Estimate your AI agent build before committing to a call.

AI Agent Estimator → Book a free call →

Common questions about AI engineering

Anything else? Book a call and we'll answer it directly.

No one can guarantee 100% accuracy from a language model, but we design systems to maximise reliability by combining retrieval-augmented generation, structured outputs, automated evals and human-in-the-loop checkpoints to keep error rates within acceptable bounds for your use case.

We are model-agnostic and work with OpenAI GPT-4o, Anthropic Claude, Google Gemini and open-weight models like Llama and Mistral. The right choice depends on your accuracy, latency, privacy and cost requirements; we will recommend the best fit after the feasibility review.

RAG (retrieval-augmented generation) fetches relevant context from your documents at inference time: great for frequently updated content. Fine-tuning trains the model on your specific data to change its behaviour or style. Most production AI products start with RAG; fine-tuning is applied later when retrieval alone is not sufficient.

We apply input sanitisation, output validation, sandboxed tool execution and least-privilege access for any agent tools. Prompt injection testing is part of our AI security review before every production deployment, and mitigations are documented in the handover runbook.

A scoped PoC typically takes 2–4 weeks. A production-ready integration with eval harnesses, monitoring and rollback takes 6–10 weeks depending on complexity, data availability and how tightly it needs to integrate with your existing infrastructure.

Not necessarily. We can deploy using managed services like AWS Bedrock, Azure OpenAI or Google Vertex AI, which minimise infrastructure overhead. For data-privacy or cost reasons we can also run open-weight models on dedicated GPU instances you own, giving you full control over your data.

Every engagement has a fixed base fee covering discovery, scoping and delivery. We agree a success metric upfront: an automation rate, a processing time target, or an accuracy threshold. The variable fee is paid only if that metric lands, measured at 60 to 90 days post-delivery using your own data. If the metric misses, you do not pay the variable portion. How our engagement model works →

Ready to take AI from experiment to production?

30 minutes. Tell us your use case, your data, and the outcome you are trying to achieve. Feasibility report within 48 hours.

Hammad Afridi (ex-BBC, Booking.com, Sainsbury's) leads every engagement.

AI Readiness Scorecard → Book a free call →